
Databricks Databricks-Machine-Learning-Professional Actual Free Exam Questions & Community Discussion
Which of the following is an advantage of using the python_function(pyfunc) model flavor over the built-in library-specific model flavors?
Correct Answer: E
Vote an answer
A data scientist would like to enable MLflow Autologging for all machine learning libraries used in a notebook. They want to ensure that MLflow Autologging is used no matter what version of the Databricks Runtime for Machine Learning is used to run the notebook and no matter what workspace-wide configurations are selected in the Admin Console. Which of the following lines of code can they use to accomplish this task?
Correct Answer: D
Vote an answer
A machine learning engineer is migrating a machine learning pipeline to use Databricks Machine Learning. They have programmatically identified the best run from an MLflow Experiment and stored its URI in the model_uri variable and its Run ID in the run_id variable. They have also determined that the model was logged with the name "model". Now, the machine learning engineer wants to register that model in the MLflow Model Registry with the name "best_model".
Which line of code can they use to register the model to the MLflow Model Registry?
Which line of code can they use to register the model to the MLflow Model Registry?
Correct Answer: E
Vote an answer
A data scientist has written a function to track the runs of their random forest model. The data scientist is changing the number of trees in the forest across each run. Which of the following MLflow operations is designed to log single values like the number of trees in a random forest?
Correct Answer: E
Vote an answer
A machine learning engineer has found drift in a production machine learning application. The engineer has determined that retraining and deploying a new model is necessary. Which statement must be true prior to deploying the new model?
Correct Answer: D
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A Data Scientist is building a machine learning pipeline to classify raw text using a Logistic Regression model in Spark using Spark MLlib's Pipelines. This pipeline has three stages: the Tokenizer (to split the raw text in tokens), a HashingTF (to transform tokens into hashes) and the Logistic Regression itself (to perform the classification of texts). The Spark DataFrame with the training data is called trainingDF and the one with the test data is called testDF.
In order to do this, they use the following incomplete piece of code:
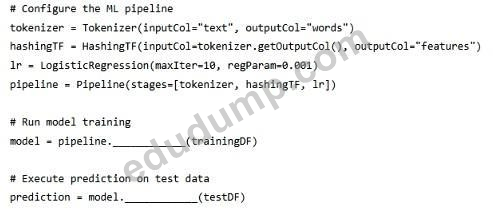
Which option correctly states:
(i) The complete command to run model training;
(ii) The complete command to execute the prediction on test data;
(iii) The object type of the model object returned by the model
training command.
In order to do this, they use the following incomplete piece of code:
Which option correctly states:
(i) The complete command to run model training;
(ii) The complete command to execute the prediction on test data;
(iii) The object type of the model object returned by the model
training command.
Correct Answer: D
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A Data Scientist needs to analyze drift detection results from Databricks Lakehouse Monitoring.
The system has generated both profile metrics and drift metrics tables. The scientist needs to identify baseline drift in numerical features by comparing current data against a baseline from 6 months ago. Which combination of table columns and values indicates baseline drift in a numerical feature?
The system has generated both profile metrics and drift metrics tables. The scientist needs to identify baseline drift in numerical features by comparing current data against a baseline from 6 months ago. Which combination of table columns and values indicates baseline drift in a numerical feature?
Correct Answer: D
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A Data Scientist is developing a model training pipeline on Databricks and needs to track custom performance metrics during training. They want to log a custom evaluation score (team_score), a single hyperparameter, and a confusion matrix plot as part of their MLflow experiment. Which code snippet correctly logs all three types of information in MLflow?
Correct Answer: B
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A retail company wants to better forecast their sales of each SKU in every store in order to more accurately distribute their products. To achieve this, a Data Scientist proposes scaling their existing forecasting model to forecast individually for each combination of SKU and Store ID.
They have a cluster with 12 executors available in order to execute this. The current model is written using Pandas and the Prophet library for forecasting, with a Python function that receives a Pandas Data Frame with historic sales data as a parameter to train the forecasting model. For their next iteration, they want to improve the efficiency of this approach while using the least amount of effort and leveraging all available resources. Which approach will do this?
They have a cluster with 12 executors available in order to execute this. The current model is written using Pandas and the Prophet library for forecasting, with a Python function that receives a Pandas Data Frame with historic sales data as a parameter to train the forecasting model. For their next iteration, they want to improve the efficiency of this approach while using the least amount of effort and leveraging all available resources. Which approach will do this?
Correct Answer: D
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
Which of the following operations in Feature Store Client fs can be used to return a Spark DataFrame of a data set associated with a Feature Store table?
Correct Answer: A
Vote an answer

0
0
0
10