
Databricks Databricks-Machine-Learning-Professional Actual Free Exam Questions & Community Discussion
A Data Scientist is building a predictive maintenance model for a fleet of vehicles. They have two tables in their feature store:
1. A sensor_readings feature table with IoT data (e.g., engine_temp,
oil_pressure) streamed continuously. This is a time-series table with
vehicle_id as a primary key and ts as a timestamp key.
2. A maintenance_logs ground truth table that records when a vehicle
component failed. This table includes vehicle_id and the exact
failure_ts timestamp.
The goal is to create a training dataset by joining sensor_readings to maintenance_logs to train a model that predicts failures. They want to join the feature data with the ground truth data to ensure point-in-time correctness and prevent data leakage during model training.
Which approach will do this?
Correct Answer: C
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
What tool helps avoid feature mismatch between training and inference?
Correct Answer: B
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A machine learning engineer has a machine learning pipeline where predictions are updated annually. The final prediction dataset contains millions of rows, and that dataset is irregularly accessed. Which solution should the machine learning engineer use to maintain cost efficiency?
Correct Answer: D
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
Which of the following Databricks-managed MLflow capabilities is a centralized model store?
Correct Answer: A
Vote an answer
Which statement is a reason for using Jensen-Shannon (JS) distance over a Kolmogorov- Smirnov (KS) test for numeric feature drift detection?
Correct Answer: B
Vote an answer
A machine learning engineer is in the process of implementing a concept drift monitoring solution.
They are planning to use the following steps:
1. Deploy a model to production and compute predicted values
2. Obtain the observed (actual) label values
3. _____
4. Run a statistical test to determine if there are changes over time
Which of the following should be completed as Step #3?
They are planning to use the following steps:
1. Deploy a model to production and compute predicted values
2. Obtain the observed (actual) label values
3. _____
4. Run a statistical test to determine if there are changes over time
Which of the following should be completed as Step #3?
Correct Answer: D
Vote an answer
A data scientist has developed and logged a Spark ML random forest model model, and then they ended their Spark session and terminated their cluster. After starting a new cluster, they want to review the featureImportances of the original model object. Which lines of code can be used to restore the model object so that featureImportances is available?
Correct Answer: C
Vote an answer
A Machine Learning Engineer is building an application that requires low latency data lookups in response to a user's question following a RAG based search. They want to ensure their users can receive as recent data as possible for urgent requests, so data should not be more than a few minutes late. The underlying data is a large table that may contain hundreds of gigabytes of data. Which data serving approach will suit their use case?
Correct Answer: A
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A machine learning engineer has developed a random forest model using scikit-learn, logged the model using MLflow as random_forest_model, and stored its run ID in the run_id Python variable.
They now want to deploy that model by performing batch inference on a Spark DataFrame spark_df. Which of the following code blocks can they use to create a function called predict that they can use to complete the task?
They now want to deploy that model by performing batch inference on a Spark DataFrame spark_df. Which of the following code blocks can they use to create a function called predict that they can use to complete the task?
Correct Answer: B
Vote an answer
A machine learning engineering manager has asked all of the engineers on their team to add text descriptions to each of the model projects in the MLflow Model Registry. They are starting with the model project "model" and they'd like to add the text in the model_description variable.
The team is using the following line of code:
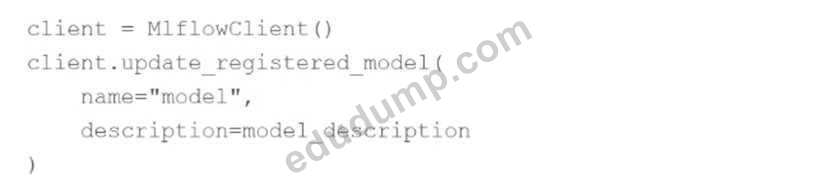
Which change does the team need to make to the above code block to accomplish the task?
The team is using the following line of code:
Which change does the team need to make to the above code block to accomplish the task?
Correct Answer: B
Vote an answer

0
0
0
10