
Databricks Databricks-Machine-Learning-Associate Actual Free Exam Questions & Community Discussion
A data scientist is using Spark ML to engineer features for an exploratory machine learning project.
They decide they want to standardize their features using the following code block:
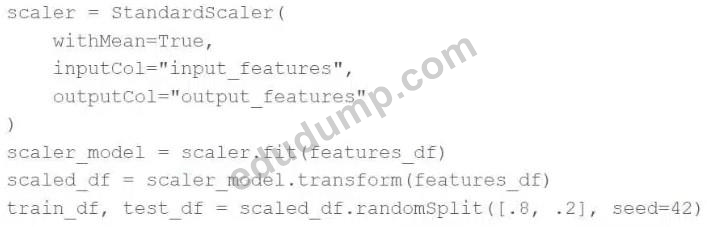
Upon code review, a colleague expressed concern with the features being standardized prior to splitting the data into a training set and a test set.
Which of the following changes can the data scientist make to address the concern?
They decide they want to standardize their features using the following code block:
Upon code review, a colleague expressed concern with the features being standardized prior to splitting the data into a training set and a test set.
Which of the following changes can the data scientist make to address the concern?
Correct Answer: C
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
The implementation of linear regression in Spark ML first attempts to solve the linear regression problem using matrix decomposition, but this method does not scale well to large datasets with a large number of variables.
Which of the following approaches does Spark ML use to distribute the training of a linear regression model for large data?
Which of the following approaches does Spark ML use to distribute the training of a linear regression model for large data?
Correct Answer: C
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
Which of the following describes the relationship between native Spark DataFrames and pandas API on Spark DataFrames?
Correct Answer: C
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A new data scientist has started working on an existing machine learning project. The project is a scheduled Job that retrains every day. The project currently exists in a Repo in Databricks. The data scientist has been tasked with improving the feature engineering of the pipeline's preprocessing stage. The data scientist wants to make necessary updates to the code that can be easily adopted into the project without changing what is being run each day.
Which approach should the data scientist take to complete this task?
Which approach should the data scientist take to complete this task?
Correct Answer: B
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A data scientist has been given an incomplete notebook from the data engineering team. The notebook uses a Spark DataFrame spark_df on which the data scientist needs to perform further feature engineering. Unfortunately, the data scientist has not yet learned the PySpark DataFrame API.
Which of the following blocks of code can the data scientist run to be able to use the pandas API on Spark?
Which of the following blocks of code can the data scientist run to be able to use the pandas API on Spark?
Correct Answer: A
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A machine learning engineer is converting a decision tree from sklearn to Spark ML. They notice that they are receiving different results despite all of their data and manually specified hyperparameter values being identical.
Which of the following describes a reason that the single-node sklearn decision tree and the Spark ML decision tree can differ?
Which of the following describes a reason that the single-node sklearn decision tree and the Spark ML decision tree can differ?
Correct Answer: D
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A data scientist has developed a machine learning pipeline with a static input data set using Spark ML, but the pipeline is taking too long to process. They increase the number of workers in the cluster to get the pipeline to run more efficiently. They notice that the number of rows in the training set after reconfiguring the cluster is different from the number of rows in the training set prior to reconfiguring the cluster.
Which of the following approaches will guarantee a reproducible training and test set for each model?
Which of the following approaches will guarantee a reproducible training and test set for each model?
Correct Answer: A
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A data scientist is developing a machine learning pipeline using AutoML on Databricks Machine Learning.
Which of the following steps will the data scientist need to perform outside of their AutoML experiment?
Which of the following steps will the data scientist need to perform outside of their AutoML experiment?
Correct Answer: B
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).

0
0
0
10