
Databricks Databricks-Machine-Learning-Associate Actual Free Exam Questions & Community Discussion
A data scientist is using the following code block to tune hyperparameters for a machine learning model:
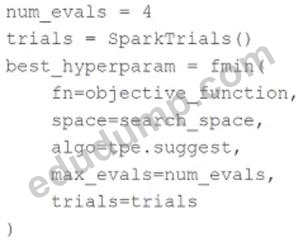
Which change can they make the above code block to improve the likelihood of a more accurate model?
Which change can they make the above code block to improve the likelihood of a more accurate model?
Correct Answer: B
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
What is the name of the method that transforms categorical features into a series of binary indicator feature variables?
Correct Answer: C
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A team is developing guidelines on when to use various evaluation metrics for classification problems. The team needs to provide input on when to use the F1 score over accuracy.
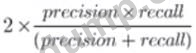
Which of the following suggestions should the team include in their guidelines?
Which of the following suggestions should the team include in their guidelines?
Correct Answer: B
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A data scientist is developing a single-node machine learning model. They have a large number of model configurations to test as a part of their experiment. As a result, the model tuning process takes too long to complete. Which of the following approaches can be used to speed up the model tuning process?
Correct Answer: C
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A data scientist has created a linear regression model that uses log(price) as a label variable. Using this model, they have performed inference and the predictions and actual label values are in Spark DataFrame preds_df.
They are using the following code block to evaluate the model:
regression_evaluator.setMetricName("rmse").evaluate(preds_df)
Which of the following changes should the data scientist make to evaluate the RMSE in a way that is comparable with price?
They are using the following code block to evaluate the model:
regression_evaluator.setMetricName("rmse").evaluate(preds_df)
Which of the following changes should the data scientist make to evaluate the RMSE in a way that is comparable with price?
Correct Answer: C
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A machine learning engineer is trying to scale a machine learning pipeline by distributing its feature engineering process.
Which of the following feature engineering tasks will be the least efficient to distribute?
Which of the following feature engineering tasks will be the least efficient to distribute?
Correct Answer: A
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
A data scientist is using MLflow to track their machine learning experiment. As a part of each of their MLflow runs, they are performing hyperparameter tuning. The data scientist would like to have one parent run for the tuning process with a child run for each unique combination of hyperparameter values. All parent and child runs are being manually started with mlflow.start_run.
Which of the following approaches can the data scientist use to accomplish this MLflow run organization?
Which of the following approaches can the data scientist use to accomplish this MLflow run organization?
Correct Answer: D
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).
Which of the Spark operations can be used to randomly split a Spark DataFrame into a training DataFrame and a test DataFrame for downstream use?
Correct Answer: D
Vote an answer
Explanation: Only visible for EduDump members. You can sign-up / login (it's free).

0
0
0
10